

When you create a cluster in Cluster Director, you must select the consumption option that you want to use to obtain resources (vCPUs, memory, GPUs, TPUs, and Local SSD disks) for creating Compute Engine instances. Each consumption option defines the availability, lifespan, and cost of your requested resources. This document compares the available consumption options, and it helps you choose the option that best fits your workload and cost needs.
Compare consumption options
The following table compares the supported machine types, lifespans, capacity assurance levels, pricing models, and reservation requirements for each consumption option:
| Consumption option | Future reservations for capacity blocks | Future reservations in calendar mode (up to 90 days) | Flex-start | Spot | On-demand |
|---|---|---|---|---|---|
| Supported machines | A4X Max, A4X, A4, A3 Ultra, A3 Mega, TPU7x*, TPU v6e, TPU v5p | A4, A3 Ultra, A3 Mega, TPU7x*, TPU v6e, TPU v5p | A4, A3 Ultra, A3 Mega, TPU7x*, TPU v6e, TPU v5p | A4, A3 Ultra, A3 Mega, TPU7x*, TPU v6e, TPU v5p, N2 | C4A, N2, TPU7x, TPU v6e, TPU v5p |
| Lifespan | Unlimited | 90 days maximum | 7 days maximum | Unlimited (but subject to preemption) | Unlimited |
| Capacity assurance | Very high | Very high | Best-effort | Best-effort | Best-effort |
| Quota | Google increases quota on your behalf | No quota is charged | Preemptible quota is charged | Preemptible quota is charged | Standard quota is charged |
| Pricing | Discounted up to 53% (accelerator pricing, TPU pricing) | Discounted up to 53% (DWS pricing) | Discounted up to 53% (DWS pricing) | Deeply discounted up to 91% (Spot pricing) | Standard pricing (VM instance pricing, TPU pricing) |
| Billing model | Charged for the reservation period (reservation billing) | Charged for the reservation period (reservation billing) | Pay-as-you-go (PAYG) | Pay-as-you-go (PAYG) | Pay-as-you-go (PAYG) |
| Resource allocation | Dense (best-effort for TPU v5p) | Dense for GPU virtual machines (VMs), best-effort for TPU VMs | Best-effort | Best-effort | Best-effort |
| Provisioning model | Reservation-bound | Reservation-bound | Flex-start | Spot | Standard |
* To obtain TPU7x VMs with any consumption option except On-demand, you must contact your account team or the sales team to request access.
If you want AI-powered assistance to compare consumption options, then run the following prompt in Compute Advisor:
This prompt evaluates your project quotas and reservations, compares capacity assurance, lifespan, and discounts across consumption options, and outputs a Markdown comparison table with recommended partition configurations.
Choose a consumption option
Use the following flowchart to choose the consumption option that best fits the type of partition for your cluster:
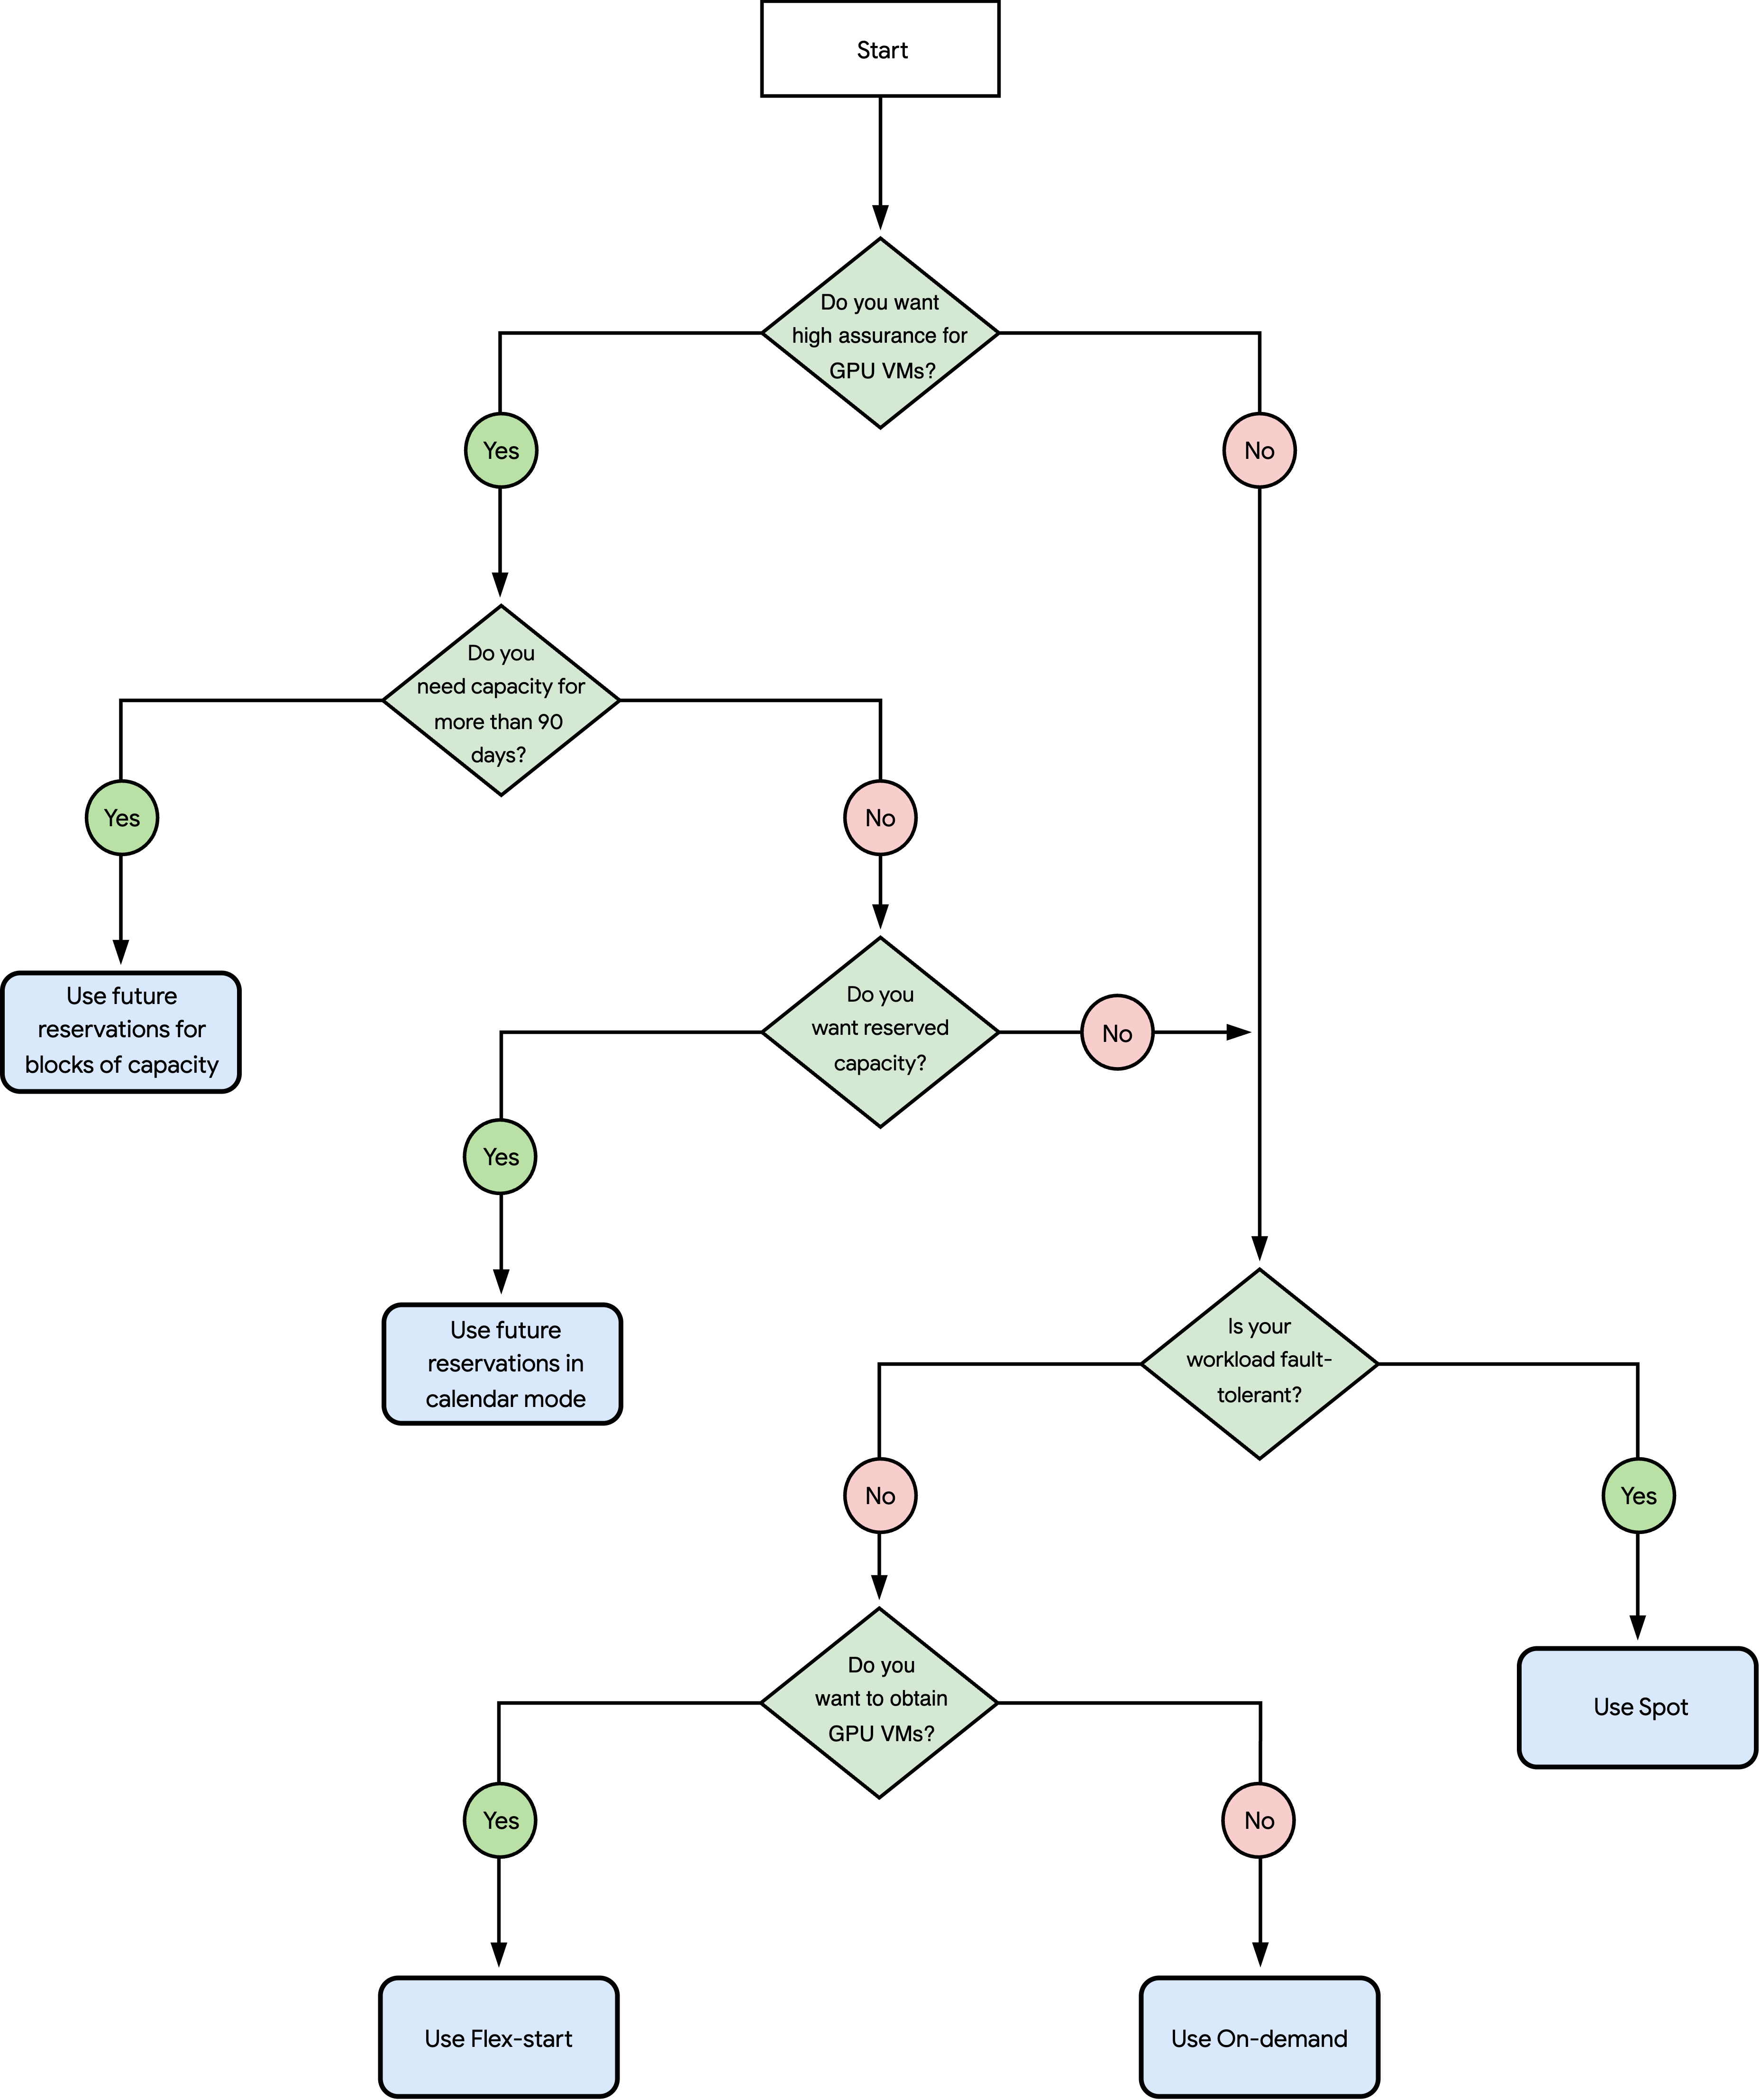
The questions in the preceding diagram are the following:
Do you want high assurance for GPU or TPU instances?
Yes: go to question 2.
No: skip to question 4.
Do you need capacity for more than 90 days?
No: go to question 3.
Do you want reserved capacity?
Yes: see Use future reservations in calendar mode.
No: go to question 4.
Is your workload fault-tolerant?
Yes: see Use Spot.
No: go to question 5.
Is your workload running for 7 days or less?
Yes: see Use Flex-start.
No: see Use On-demand.
Use future reservations for capacity blocks
To run long-running, large-scale distributed workloads that require densely allocated resources, you can reserve vCPUs, memory, GPUs, TPUs, Local SSD disks, and a Hyperdisk pool for a future period. If Google approves your request, then you have exclusive access to your reserved resources for that period of time, and you can use the resources to create clusters. At the end of the reservation period, Compute Engine does the following:
Compute Engine deletes the reservation and any associated empty Hyperdisk pool.
Compute Engine deletes any compute instances in your cluster that use the reservation.
Ideal workloads for future reservations for capacity blocks
Future reservations for capacity blocks are ideal for the following workloads:
Pre-training foundation models
Inference for foundation models across multiple hosts
Characteristics of future reservations for capacity blocks
Future reservations for capacity blocks have the following characteristics:
You can reserve A4X Max, A4X, A4, A3 Ultra, A3 Mega, TPU7x, TPU v6e, and TPU v5p machine types, as well as Hyperdisk pools. For GPU, TPU7x, and TPU v6e VMs, Google allocates compute nodes in close physical proximity to minimize network latency, and co-locates Hyperdisk pools with those compute nodes to optimize storage performance.
You can reserve as many compute instances as you want for as long as you want. For any compute instances that you want to reserve for a year or longer, you need to purchase and attach a resource-based commitment to your reserved resources. Then, you can use the reserved resources to create and run compute instances until the end of the reservation period.
You use the reservation-bound provisioning model to create compute instances, which has the following benefits:
You have a higher chance to obtain GPUs or TPUs.
In addition to the commitment that is attached to your compute instances, you get a discount up to 53% for vCPUs, memory, GPUs, TPUs, and any attached Local SSD disks. If you reserve resources for 365 days or longer, then you also get discounts for Hyperdisk pools.
How to use future reservations for capacity blocks
To use future reservations for capacity blocks to create clusters, you must complete the following steps:
Request to reserve capacity. Contact your account team and specify the compute instances and Hyperdisk pools to reserve. Based on availability, Google creates a draft reservation request for you. If the draft matches your requirements, then accept and submit the request. If you reserve compute and storage capacity together, then you must accept both requests as a bundle to ensure that Google delivers both resources at the same time. Google Cloud approves your reservation request within a few minutes.
For instructions, see Reserve capacity through your account team.
Consume reserved resources. At the start of your reservation period, Google delivers your compute reservation and Hyperdisk pools. You can use the reserved resources to create compute instances and attach storage disks in one or more of your cluster partitions. For A4X, TPU7x, and TPU v6e reservations (in all-capacity mode for TPUs), you can also select specific blocks or sub-blocks to control the placement of your VMs.
For instructions, see one of the following:
Use future reservations in calendar mode
To run short-running distributed workloads that require densely allocated resources, you can request to reserve compute resources for up to 90 days. If Google approves your request, then you have exclusive access to your reserved resources for that time, and you can use the resources to create clusters. At the end of the reservation period, Compute Engine does the following:
Compute Engine deletes the reservation.
Compute Engine deletes any VM instances that use the reservation.
Ideal workloads for future reservations in calendar mode
Future reservations in calendar mode are ideal for the following workloads:
Model pre-training
Model fine-tuning
Simulations
Inference
Characteristics of future reservations in calendar mode
Future reservations in calendar mode have the following characteristics:
You can reserve A4, A3 Ultra, A3 Mega, TPU7x*, TPU v6e, or TPU v5p machine types. Google densely allocates GPU VMs to minimize network latency, and allocates TPU VMs as close to each other as possible on a best-effort basis.
You can view the future availability of resources, and then reserve GPU or TPU capacity for up to 90 days. At your chosen delivery date, you can use the reserved resources to create VMs until the end of the reservation period. For supported request sizes and locations, see Limitations for future reservation requests in calendar mode in the Compute Engine documentation.
You use the reservation-bound provisioning model to create compute instances, which has the following benefits:
You have a higher chance to obtain GPUs or TPUs.
You get a discount up to 53% for vCPUs, memory, GPUs, TPUs, and any attached Local SSD disks.
How to use future reservations in calendar mode
To use future reservations in calendar mode to create clusters, you must complete the following steps:
View resource availability. You can view the future availability of the resources that you want to reserve. When you create a reservation request, you can specify the number, type, and reservation duration for the resources that you confirmed as available. This action increases the chances that Google Cloud approves your request.
For instructions, see View the future availability of resources.
Reserve capacity. You create a reservation request for a future date and time. Google Cloud approves the reservation request within two minutes. If Google Cloud approves the request, then Compute Engine reserves the capacity for you. At your chosen delivery date, you can use the reserved resources to create clusters.
For instructions, see Create a request for GPU VMs, H4D VMs, or TPUs.
Consume reserved resources. At the start of your chosen reservation period, you can use the reservation to create VMs in one or more of your cluster partitions.
For instructions, see one of the following:
Use Flex-start
To run short-duration workloads that require densely allocated resources, you can request compute resources for up to seven days by using Flex-start. Whenever resources are available, Compute Engine creates your requested number of VMs. The Flex-start VMs run until you delete them, or until Compute Engine deletes the VMs at the end of their run duration.
Ideal workloads for Flex-start
Flex-start is ideal for workloads that can start at any time, such as the following:
Small model pre-training
Model fine-tuning
Simulations
Batch inference
Characteristics of Flex-start
Flex-start has the following characteristics:
You can request A4, A3 Ultra, A3 Mega, TPU7x, TPU v6e, and TPU v5p VMs. For TPU VMs, Cluster Director provisions all VMs within a slice together on a 2D or 3D interconnect topology; slice availability and dense allocation across nodes depend on resource availability.
You use the flex-start provisioning model to create Flex-start VMs, which has the following benefits:
You have a higher chance to obtain GPUs or TPUs.
You get a discount up to 53% for vCPUs, memory, GPUs, TPUs, and any attached Local SSD disks.
You can request resources for up to seven days. When your allocated resources reach the end of their maximum run duration, Cluster Director automatically requests new resources with the same run duration.
How to use Flex-start
To use Flex-start to create VMs in one or more of your cluster partitions, use one of the following methods:
Use Spot
To run fault-tolerant workloads, you can obtain compute resources immediately based on availability. You get resources at the lowest price possible. However, Compute Engine can preempt Spot VMs at any time to reclaim capacity.
Ideal workloads for Spot
Spot is ideal for workloads where interruptions are acceptable, such as the following:
Batch processing
High performance computing (HPC)
Continuous integration and continuous deployment (CI/CD)
Data analytics
Media encoding
Online inference
Characteristics of Spot
Spot has the following characteristics:
You can create A4, A3 Ultra, A3 Mega, TPU7x, TPU v6e, TPU v5p, and N2 VMs. For TPU VMs, Cluster Director provisions all VMs within a slice together on a 2D or 3D interconnect topology; slice availability and dense allocation across nodes depend on resource availability.
You can immediately create clusters. Unless Compute Engine preempts the VMs to reclaim capacity, GPU and N2 VMs run until you stop or delete them, and TPU VMs run until you delete them.
You use the spot provisioning model to create Spot VMs, which has the following benefits:
You have a higher chance to obtain GPUs or TPUs.
You get a discount up to 91% for vCPUs, memory, and any attached GPUs, TPUs, and Local SSD disks.
How to use Spot
To use Spot to create VMs in one or more of your cluster partitions, complete the following steps:
View resource availability. You can view the availability of A4, A3 Ultra, A3 Mega, and N2 machine types in the region or zone where you want to create Spot VMs. This action helps reduce the time that Cluster Director takes to allocate resources and create Spot VMs.
For instructions, see View resource availability for Spot VMs.
View preemption rate and pricing. You can view the historical and current preemption rate and pricing across A4, A3 Ultra, A3 Mega, and N2 machine types and zones. This information helps you choose the machine type and location that best fit your workload and budget.
For instructions, see View the preemption rate and pricing for Spot VMs.
Create your cluster. To create your cluster with one or more partitions that use Spot VMs, select one of the following methods:
Use On-demand
To run TPU workloads without a reservation or cluster components without GPU or TPU acceleration (such as login nodes), you can obtain on-demand resources based on availability at standard pricing.
Ideal workloads for On-demand
On-demand is ideal for the following workloads:
TPU training and inference workloads
Login nodes
CPU-bound computational tasks
General-purpose HPC
Characteristics of On-demand
On-demand has the following characteristics:
You can create C4A, N2, TPU7x, TPU v6e, and TPU v5p VMs. Cluster Director provisions TPU VMs in a slice together on a 2D or 3D interconnect topology. For C4A and N2 VMs, dense allocation depends on resource availability. You can use C4A VMs only for login nodes.
You can immediately create clusters. C4A and N2 VMs run until you stop or delete them, and TPU VMs run until you delete them.
You use the standard provisioning model, which is the default model.
How to use On-demand
To use On-demand to create VMs in one or more of your cluster partitions, use one of the following methods: